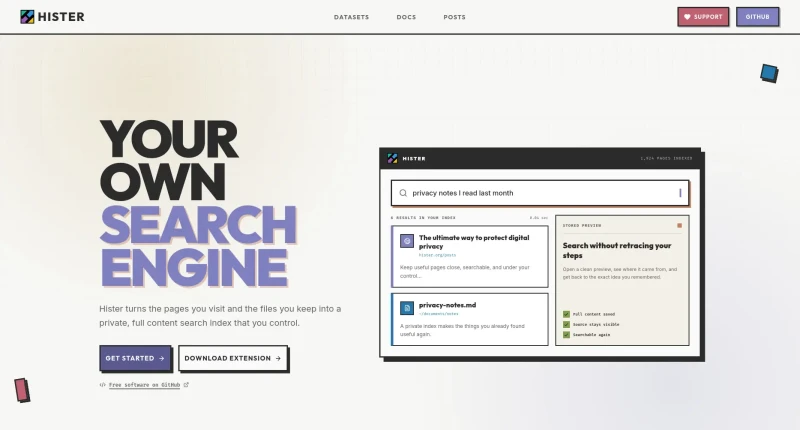
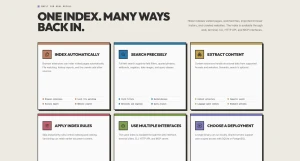
Hister turns the pages you visit and the files you keep into a private, full content search index that you control.
Hister is an open-source (AGPLv3), self-hosted personal search engine that turns visited web pages, local files, browser history, and crawled websites into a private, full-text search index under your control.
The main features and capabilities of Hister include:
Multi-Source Data Ingestion: Collects and indexes content automatically via browser extensions (Chrome and Firefox) as you visit pages, file system watchers on local folders, browser history imports, or site crawlers.
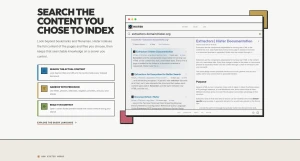
Full-Content Extraction & Previews: Indexes the full text of documents—moving beyond basic filenames or titles—and stores clean, readable content previews alongside search results.
Precision Querying & Index Rules: Supports field filters, quoted phrases, wildcards, negation, date ranges, and custom query aliases, alongside priority ranking, skip rules, sensitive content checks, and content versioning.
Multi-Interface & MCP Integration: Accessible through a web interface, terminal client, HTTP API, CLI, and a Model Context Protocol (MCP) server for direct AI assistant retrieval.
Privacy & Flexible Deployment: Operates with zero telemetry or mandatory cloud connections on a single local machine or a multi-user server using SQLite or PostgreSQL. Deployment is supported via single binaries, Docker, or Nix, with optional semantic search through custom embedding endpoints.
You may also be interested in ...
Plotly
Paged.js